Resume Parsing: Where It Works, and Where It Quietly Fails
Resume parsing turns a CV into searchable candidate fields. When it works, a recruiter gets a usable record without typing out the candidate’s work history. When it fails, the record can still look complete.
A two-column layout might attach dates to the wrong employer. An old contract might appear to be the candidate’s current role. The profile stays in the database, and searches built on title, employer, or tenure quietly miss the person.
That is the costly part of resume parsing: errors you cannot see by looking at the search results. This guide explains where parsing is reliable, where it breaks, how to check your existing records, and what to do when the CV leaves out information your firm already knows.
What resume parsing actually does
Resume parsing extracts structured fields from an unstructured document. The parser reads a CV and writes name, contact details, employers, job titles, date ranges, education and a skills list into database fields.
It is an extraction task, not a candidate assessment. The parser is not deciding whether someone fits a brief. It is deciding which information belongs in which field.
That distinction explains almost everything that follows.
Where resume parsing works well
Give it a conventional, single-column, recently written CV and modern parsing can save substantial data entry.
Contact details, employer names, date ranges, education and skills lists are easier to extract when they follow a familiar layout. For the bulk of a database this is useful, and it saves hours of typing that nobody should be doing.
Where resume parsing quietly fails
The failures cluster in five places, and many do not announce themselves.
Layouts the parser cannot read in order
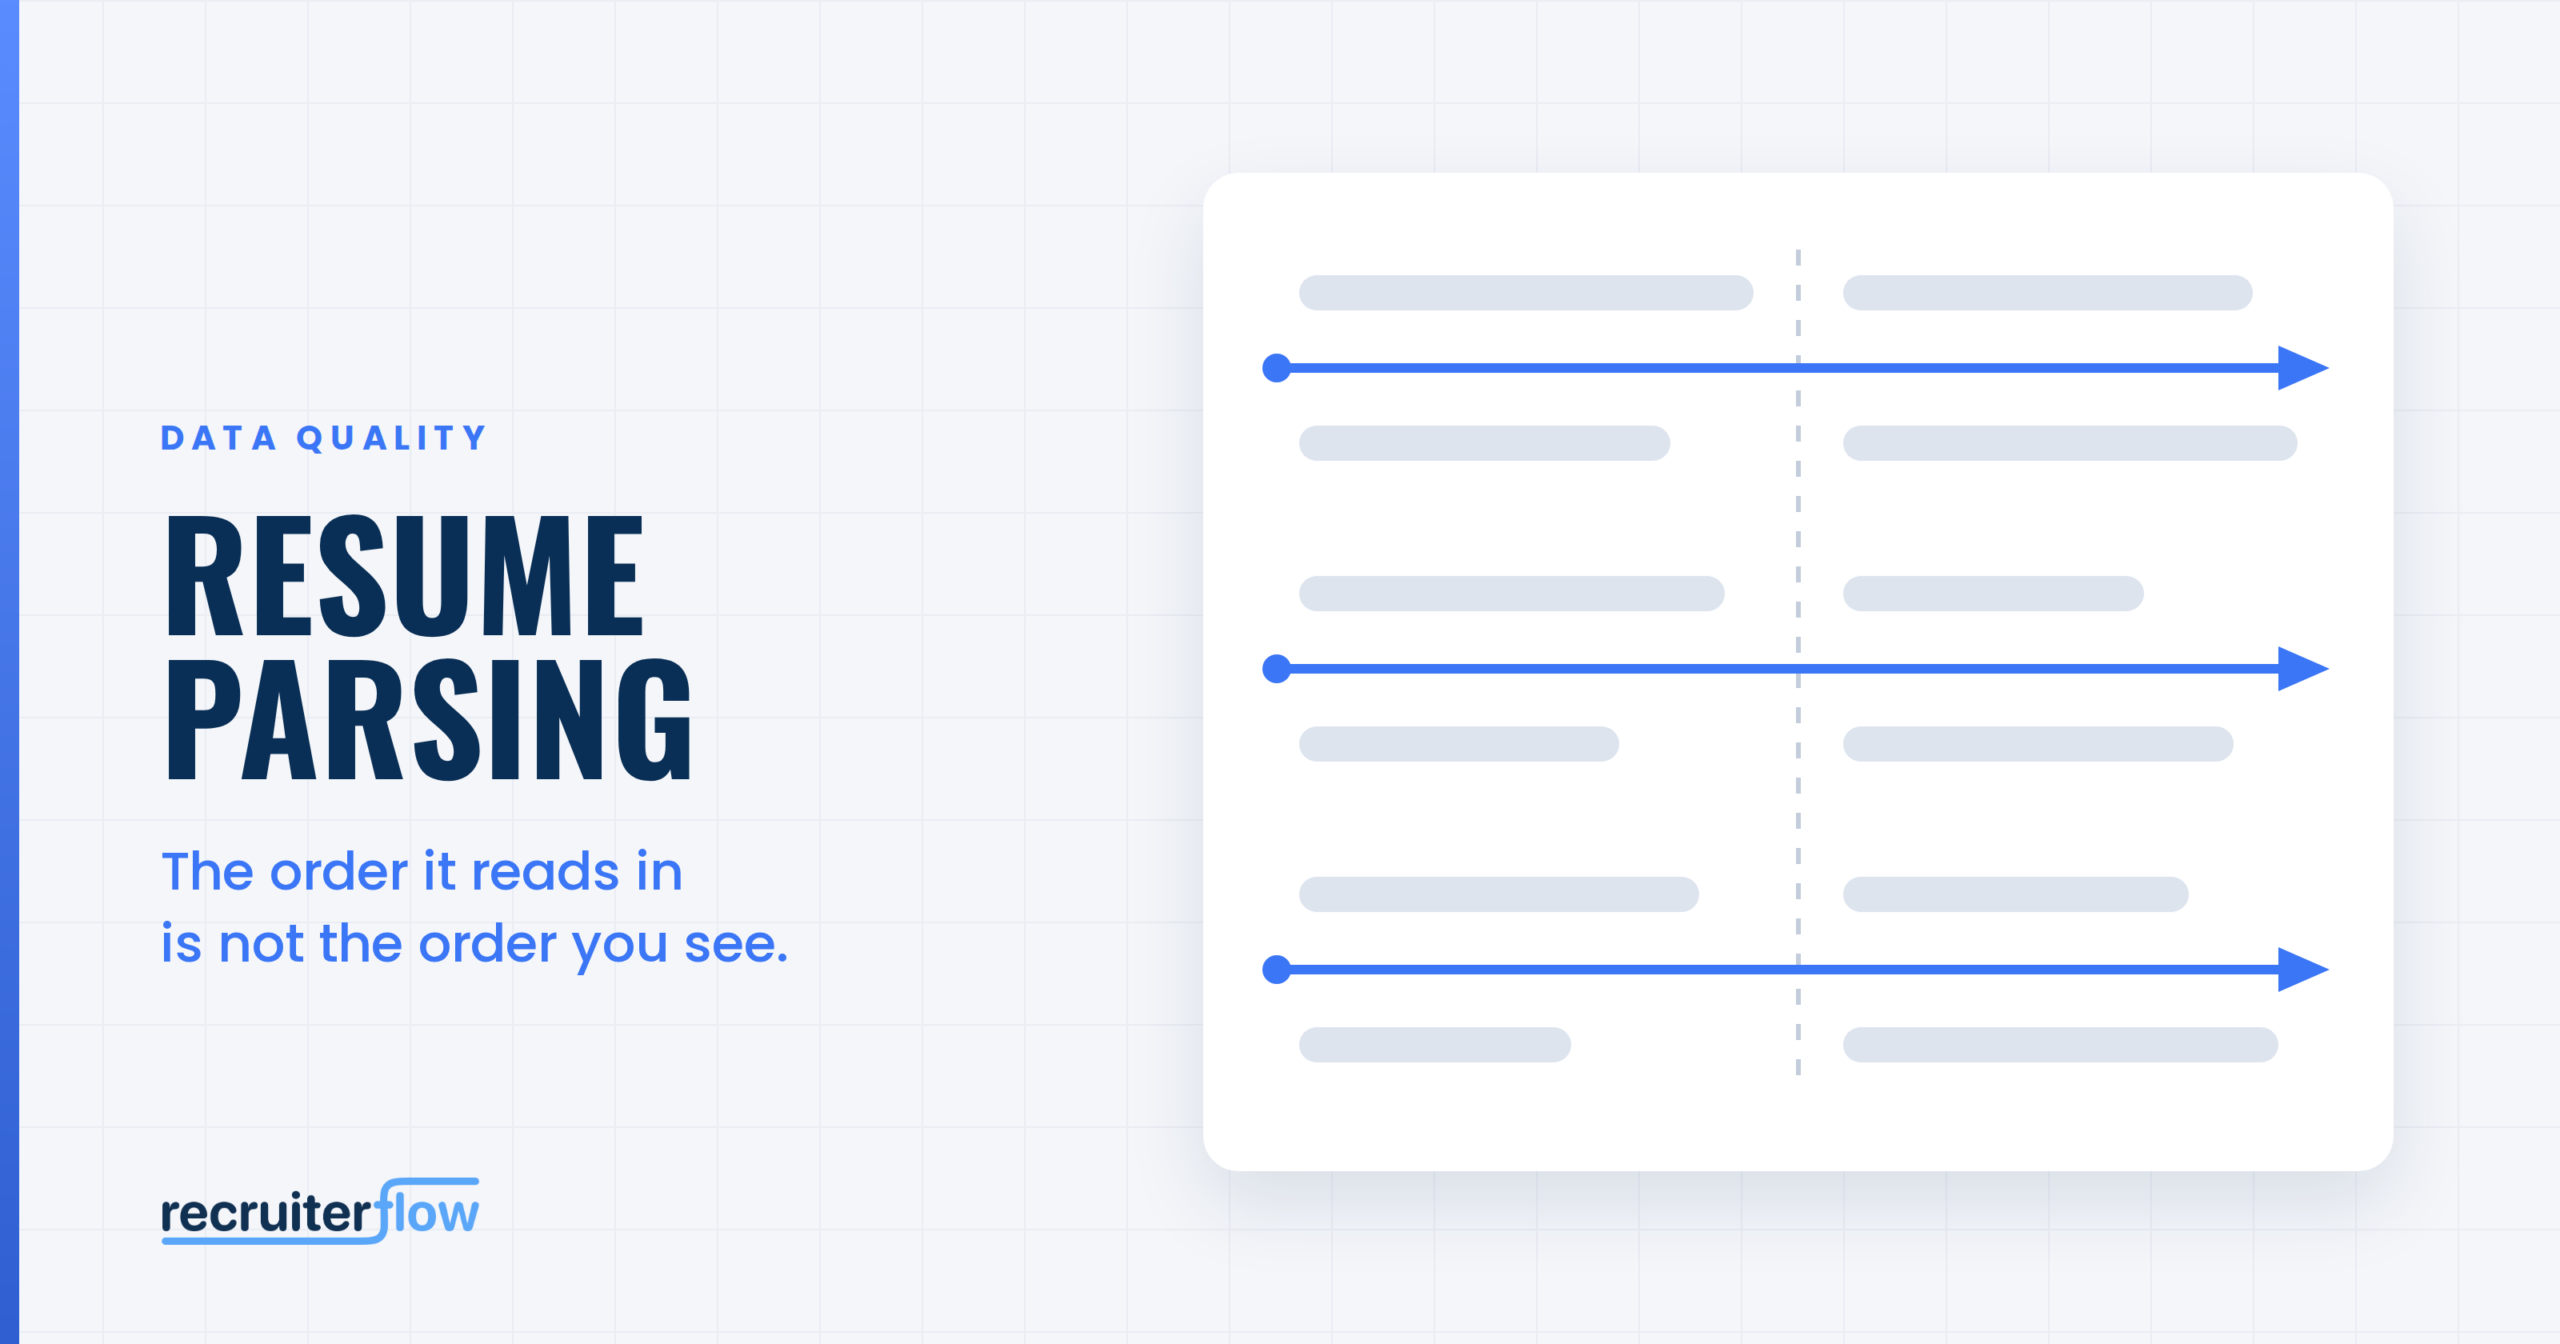
Two-column CVs, tables, text boxes, and PDFs exported from design tools can break reading order. The parser may take text in the order the file stores it, which is not always the order a human eye follows.
The result can be dates attached to the wrong employer, or a skills column interleaved into the work history. The record looks populated. It is simply wrong.
Careers that are not a straight line
Contract and interim careers can parse badly. When five assignments sit under one umbrella company, a parser may see one employer and a five-year tenure, when the truth is five clients and five different scopes.
Career breaks, internal promotions listed under a single employer block, and portfolio careers can produce the same effect: a tidy record that misrepresents what the person actually did.
Titles that do not mean what they say
A parser can extract “Vice President” perfectly and still leave you with an unhelpful field, because Vice President at a bank and VP at a twelve-person startup are not the same job.
Parsing captures the string. Seniority is a judgment about scope, budget and reporting line, and the title alone cannot establish it.
Skills lists that flatten context
A parser extracts “Python” identically whether the candidate built production systems in it for a decade or listed it after taking a course.
The skills field tells you a word appeared. It does not tell you the person can do the thing, and searching on it returns everyone who typed it.
Anything requiring inference
Whether someone actually owned a number, whether they built a function or inherited it, whether a move to a smaller company was a step up or a step out. The CV frequently does not say. A parsed field cannot reliably answer what the source never established.
These are the questions that decide a shortlist, and they are exactly the ones parsing alone cannot answer.
Why quiet failures are expensive
A parsing error is not a one-time cost. It can persist in the record, and every field-based search afterwards inherits it.
If some of your database has the wrong current title, every search built on current title misses those people. You do not see the misses. You see a shorter result list and conclude the market is thin.
That matters because around 71% of placements come from candidates already in the database before the job opened (Source: The Economics of Recruiting). A database-first recruiting strategy depends on being able to find the people you already know.
Firms often discover these issues during a database audit, when someone opens a sample of records and reads them against the original files.
What to ask before you buy a parser
Vendor accuracy figures are measured on the vendor’s test set, which is not your database. Four questions are more useful than any percentage.
- What happens to multi-column and table layouts? Ask to see a parse of a two-column CV rather than a clean one.
- How is the current role determined, and what happens when an end date says “Present” on a contract that ended last year?
- Are umbrella companies and contract assignments separated, or collapsed into one employer?
- Can we correct a field once and have it stay corrected, or does the next re-parse overwrite it?
The last one matters. If a parser re-runs on document upload, check whether manual corrections remain intact.
What to do about it
Audit a sample rather than the whole database
Pull fifty records at random. Open each against the original CV and check four fields: current employer, current title, most recent date range, and total tenure.
Count the errors by field. That gives you a practical estimate of parse quality in your own database.
Fix the fields your searches actually depend on
You cannot re-verify a hundred thousand records, and you do not need to. Prioritize the fields your recruiters filter on most often, starting with current title and current employer. Document which records have been checked, so a later upload does not silently undo the work.
Stop treating the CV as the whole record
This is the structural fix. The CV is one document, written by the candidate, for a different purpose, possibly years ago. The rest of what your firm knows sits in call notes, emails and transcripts, and none of it is necessarily captured in parsed fields.
AIRA Search in Recruiterflow searches structured fields and unstructured information such as notes and call transcripts. A candidate who mentioned on a call that they ran a new business line can therefore surface even if their CV never said so. Results include supporting evidence so a recruiter can check why someone matched.
Parsing still writes the fields. It stops being the only information search can use. The same principle applies when choosing AI screening tools: ask what the tool reads, not just what it extracts.
Check your own parse quality this week
Take fifty records and check the four fields above against the original CVs. If more than one in ten has an error in current title or current employer, investigate how many searches rely on those fields and which candidates may be missing from the results.
Bring that sample to a demo and we will show you what the same database looks like when search can read notes and transcripts alongside parsed fields.
FAQs
What is resume parsing?
Resume parsing is the automatic extraction of structured data from a CV into database fields such as name, employer, job title, dates, education and skills. It converts an unstructured document into records a system can filter and search.
How does resume parsing work?
The parser identifies sections of the document, classifies the text within them, and maps each piece to a field. Modern systems may use machine learning to handle variation in layout and wording, but a parsed field should still be checked when it affects a search or selection decision.
How accurate is resume parsing?
Accuracy varies by document format, layout, language and the field being extracted. The useful question is the error rate on your own records, measured by checking a representative sample against the original files.
What are the limitations of resume parsing?
It cannot reliably judge seniority or infer scope from a title alone, and it cannot extract information the CV never states. Some errors create plausible-looking fields, so they remain undetected until someone checks the original document.
Can resume parsing replace screening?
No. Parsing populates fields; screening is a judgment about fit against a brief. Parsing can reduce data entry, but assessment still needs agreed criteria and a review of the evidence.
Does resume parsing work on PDFs?
It can work on text-based PDFs. A scanned image without a readable text layer may need OCR, and complex layouts can cause text to be read in the wrong order.
Recruitment
Ayusmita is a B2B storyteller who spends her time translating recruiting workflows into clear stories at Recruiterflow.
Ayusmita